
Nama ERP MCP Server
MCP (Model Context Protocol) is the open standard AI assistants — such as Claude Desktop, Claude Code, and others — use to connect to external systems, read their data, and act on them. Nama ERP ships with a built-in MCP server: once the AI module is installed, any MCP client can connect to the system directly and use the tools defined on the AI Tool Definition screen — searching records, reading documents, running reports, and even importing new records — all under a real user account with the full security model applied.
Prefer to watch?
The video guide on Getting Better Support with an AI Assistant sets up this server from scratch with Claude: the tool definitions, one API key per user, the connection file, and a live session as an administrator and as a sales manager.
Requirements
- The AI module installed and licensed — without it, the server is not mounted at all.
- If the licence carries an end date for the MCP subscription, that date must not have passed — after it, every request is refused (see Messages you may see).
- A committed API Credentials record (Basic → Documents → API Credentials — the same credentials used with the REST API).
- At least one committed tool defined on the AI Tool Definition screen.
Server Endpoint
The server uses the Streamable HTTP transport at:
http[s]://<server-ip-or-domain>/basic-services/mcpUpgrading from older versions
Older versions exposed the server over the SSE transport at /basic-services/mcp/sse. That endpoint has been replaced — update existing client configurations to the new URL and change the transport type from sse to http.
Authentication
The server authenticates every request using API credentials:
| Header | Value | Required |
|---|---|---|
X-API-Key | The API Key (Client Secret) of the API Credentials record | Yes |
Authorization | Bearer <client secret> — an alternative to X-API-Key | No |
X-API-Secret | The API Key (Client Secret), only when X-API-Key carries the record's Client Id (Can Be Ignored) instead | No |
(The values are also accepted under the alternative names: apiKey/clientId for the access key and apiSecret/clientSecret for the secret — as a header or as a URL parameter.)
A bearer token works too — releases dated 20260922 or later
Some clients cannot send a header of your own choosing and always authenticate the way the rest of the web does, with Authorization: Bearer <token>. Anthropic's MCP connector — the feature that lets Claude reach an MCP server straight from the Claude API — is the common case: it offers no way to send X-API-Key.
Put the Client Secret in the bearer token and the server accepts it; it looks at Authorization only when the request carried no X-API-Key, so nothing changes for clients that already work. Servers older than release 20260922 ignore the header and answer with an authentication failure.
The API Credentials record maps the credentials to a specific user through its User field, and supports a validity window (Valid from / Valid to) and disabling (Prevent Login (Includes POS, Apps, and All Other System Components)). The key is shown once, when the record is first saved; tick View API Key and save to see it again. Every tool the client calls executes as that user: record security, dimensions (legal entity, branch, ...), and validation rules all apply exactly as if the user were working from the system screens.
Choosing the login context
A call normally runs in the user's own login context — the legal entity, sector, branch, department and analysis set the user would land in on the login screen. Every tool also accepts five optional arguments that change that for one call: loginLegalEntity, loginSector, loginBranch, loginDepartment and loginAnalysisSet, each given as the dimension's code or id. A dimension left out keeps the user's own value.
This is how you check something "as legal entity 02": run the report, or read the document term, with loginLegalEntity = 02, and anything that depends on the login context — a report whose default filter is the user's legal entity, for example — behaves as it would for someone logged in there. The same rules as the login screen apply, so a context the user may not log in to is refused and the tool does not run; a code that matches no dimension is refused the same way. You do not define these arguments on the tool definition: every tool gets them.
Protect the credentials
An MCP client connected with these credentials can do everything the mapped user can — including creating records if the import tools are enabled. Dedicate a user with carefully measured permissions for this purpose, and restrict sensitive tools through the access-control grid on the tool definition.
Client Setup
Claude Desktop's Code tab or Claude Code — the recommended setup
The way we recommend working is the one described in Getting Better Support with an AI Assistant: Claude Desktop's Code tab — or Claude Code in a terminal — opened inside the support knowledge-base folder, so the assistant has the documentation, the data model and the live system side by side. Both read their MCP servers from a .mcp.json file in the folder they are opened in, so add the server to .mcp.json in the knowledge-base folder (create the file if it is not there):
{
  "mcpServers": {
    "nama-erp": {
      "type": "http",
      "url": "https://my-server.example.com/basic-services/mcp",
      "headers": {
        "X-API-Key": "<client-secret>"
      }
    }
  }
}
Start a new session after saving the file, and allow the server when you are asked to; in Claude Code, /mcp lists the servers and reconnects one. Several Nama servers can sit side by side in the same file, each under its own name. The Code tab and Claude Code connect from your own machine, so a customer server on a private network works as long as your machine can reach it — over the customer's VPN, for example.
Do not put the server in Claude Desktop's claude_desktop_config.json: that file is for servers the app starts on your machine, and it ignores a remote server such as Nama's.
Claude's MCP connector
Claude can also reach the server straight from the Claude API, with no MCP client of yours in between. That connector authenticates only with a bearer token, so give it the endpoint URL and put the credential's Client Secret in its authorization-token field — there is no place to add X-API-Key. This needs a server on release 20260922 or later.
MCP Inspector
The protocol's official inspector works straight from the browser (the server allows CORS requests): choose the Streamable HTTP transport, enter the URL, and add the authentication header.
After connecting, list the tools from the client — you will find every committed, non-inactive tool from the AI Tool Definition screen that the credential's user is allowed to run (a tool the access-control grid prevents for that user is not listed at all), and any change to the definitions is picked up automatically on the next connection.
Not just the export tools
The server exposes every committed tool the linked user is allowed to use — query, report, entity-flow, and system tools — not only the export tools. This page details the export tools because of their importance with external clients; the other types are documented in AI Tool Definitions.
Some tools ask you before they act
A few tools do something that cannot be taken back — upgrading the server, which stops it for everyone, is the one today. Those tools do not act on the assistant's request alone: the client shows you a confirmation form, and only your answer, sent straight back to the server, lets them go ahead. Claude Code shows these forms. A client that cannot show them gets a refusal, and nothing happens. See Server administration tools.
The Record Export/Import Tools
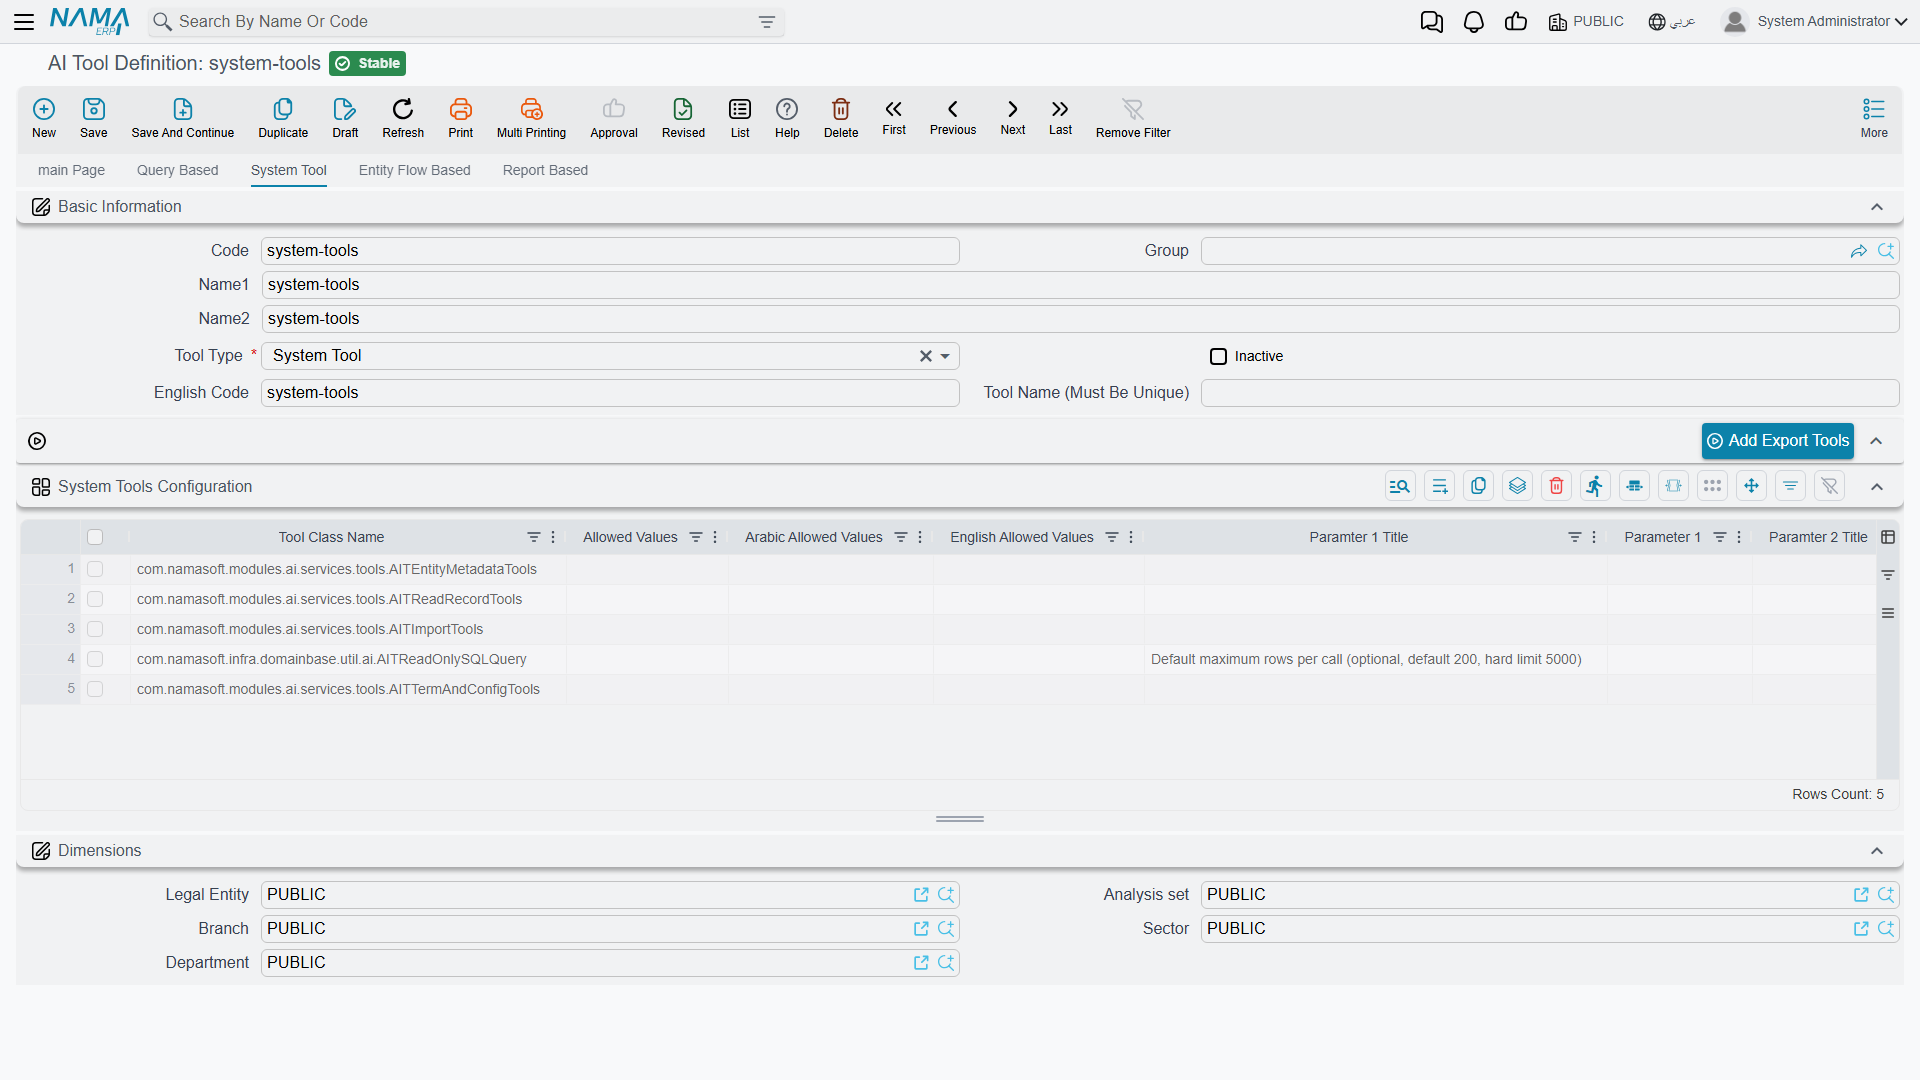
The most useful group for external MCP clients is the export/import system tools — twelve of them, from four tool classes, all added in one click with the Add Export Tools button on the System Tool page of the tool definition screen (see AI Tool Definitions).
The tools are named with a prefix taken from the tool definition (the Tool Name, Alt Code, or code field). The examples below assume the prefix is import.
import_ResolveEntityType — resolve a term to an entity type
The starting point for any client that does not know Nama's internal entity names. Send an Arabic or English term and receive the matching entity types with their translated names.
| Parameter | Required | Description |
|---|---|---|
query | No | The term to search for, such as فاتورة مبيعات or sales invoice. Leave it out, or send *, to browse the whole list instead |
page | No | 1-based page number, for browse mode |
pageSize | No | Page size for browse mode — default 50, maximum 200 |
Returns up to 25 matches, each carrying entityType (the internal name such as SalesInvoice) plus the Arabic and English names. In browse mode it returns totalEntityTypes and the requested page of them. The entityType value it gives back is the canonical one and can be passed verbatim — it is case-sensitive — to every other tool.
import_DescribeFields — the fields you may filter on
Lists the fields of an entity that can be used as FindRecords criteria, each with its type, whether it is required, the allowed values of an enum, the target entity of a reference, and the collection it belongs to.
| Parameter | Required | Description |
|---|---|---|
entityType | Yes | The entity type to describe, such as SalesInvoice |
collections | No | Detail collections to include as well (comma-separated names, such as details, the lines of a sales invoice) — header fields are always included |
This is not the same list as GetImportSchema: it also carries system fields such as creationDate, which can be searched on but never imported, and it flags calculated fields, which may not be filterable at all.
import_SearchByTranslation — find an entity, a field or an option by its name
The widest of the discovery tools: one Arabic or English term in, and everything it could mean out — entity types, fields of any entity, and enum constants, each with both its names.
| Parameter | Required | Description |
|---|---|---|
query | Yes | The Arabic or English term to look for |
limit | No | Maximum matches to return — default 25, maximum 100 |
Every match carries a kind: entity (with its entityType), field (with the entityType and fieldId) or enum (with the enumType and value). Use it when you know what the user called something but not which of the three it is.
import_FindRecords — search records
A paged search over an entity type's records, going through the standard list gate so list security and dimension filtering apply.
| Parameter | Required | Description |
|---|---|---|
entityType | Yes | The entity type, such as SalesInvoice |
criteria | No | A Nama text-criteria filter — each condition is fieldId,operator,value,logic;, such as code,Equal,INV-1,AND; or valueDate,GreaterThanOrEqual,01-01-2024,AND; (dates use dd-MM-yyyy) |
fields | No | Extra field ids to return in each row (comma-separated) — id and code are always returned |
orderBy | No | A field id to order by |
page | No | 1-based page number |
pageSize | No | Page size — default 25, maximum 200 |
Returns totalRecordsCount, the page number and size, and the records array. An attachment field asked for in fields comes back as {"id", "fileName", "size"} — the file's description, never its contents — and fields accepts a detail-table field too (collection.field), so one call can list every line's attachment; the id is what PrepareAttachmentDownloadById takes.
import_GetRecord — read a record
Reads a single record as JSON through the standard read gate. The output has the same shape used for import, so a record can be read, edited, and imported back.
| Parameter | Required | Description |
|---|---|---|
entityType | Yes | The entity type |
idOrCode | Yes | The record's business code or id |
mode | No | visible (default): only on-screen fields — or all: every field |
fields | No | Specific field ids to return on their own (overrides mode) |
An attachment field is returned as {"id": "...", "fileName": "...", "size": 123} (size in bytes); the file's contents are never included. Sending that object back unchanged in ImportRecord leaves the attachment as it is.
import_GetEnumValues — allowed values of an enum field
| Parameter | Required | Description |
|---|---|---|
entityType | Yes | The entity type owning the field |
fieldId | No | The field id, such as details.transItemType (the line type of a sales invoice line). Accepts several, comma-separated; leave it out to get every enum field of the entity |
Returns the value list with each value's Arabic and English titles — useful before importing, to send the correct constants.
import_GetEntitySchema — the tables and columns behind an entity
Where the other tools speak in field ids, this one answers in SQL: the entity's table name, its columns with their types and — for a reference column — the entity it points at, its foreign-key columns, and the same for every detail collection, including the child table and the column that joins it to the header.
| Parameter | Required | Description |
|---|---|---|
entityType | Yes | The entity type, such as SalesInvoice |
You need it when you are writing something that queries the database directly rather than going through the entity gates — a read-only SQL tool, or a report.
import_GetImportSchema — the import schema
Describes how to build a record for an entity type: every field with its type and whether it is required, the allowed values of enum fields, the target entity type of reference fields (references are written by code), and the nested structure of detail collections (such as invoice lines).
| Parameter | Required | Description |
|---|---|---|
entityType | Yes | The entity type |
mode | No | visible (default): on-screen fields — what a user would normally fill — or all: every importable field |
collections | No | Limit the returned detail collections (comma-separated names, such as details) — header fields are always included |
The response also carries an example: a skeleton record with placeholder values in exactly the shape ImportRecord expects. Amounts and quantities keep their real nesting rather than dotted keys — a journal-entry debit, for instance, is "debit": { "value": { "amount": 1500, "currency": "EGP" }, "rate": 1, "localAmount": 1500 }. Date fields carry a format hint: a date is written day-first as dd-MM-yyyy or ISO as yyyy-MM-dd, and a date-and-time as yyyy-MM-dd'T'HH:mm (a date alone is taken as midnight).
import_ImportRecord — import records
Imports one or more records in Nama's JSON format: an object keyed by entity type, each key holding an array of records.
| Parameter | Required | Description |
|---|---|---|
recordsJson | Yes | The records to import |
importMode | Yes | CreateOnly: only add records — a code that already exists is an error; UpdateOnly: only change existing records — an unknown code is an error; CreateOrUpdate: allow both. Records are matched by code, so CreateOnly is the safe choice whenever the intent is to add |
saveAsDraft | No | true: save as an uncommitted draft — false (default): save and commit |
appendDetailLines | No | Only matters when an existing record is updated: true keeps its current detail lines and adds the sent ones after them — false (default) replaces them, so any line not sent is lost |
Codes. A document whose book numbers automatically (or a master file whose group does) needs no code: leave it out and the real number is assigned on commit. A placeholder that starts with the book prefix and ends in @draft — JE1000@draft, say — is accepted too and replaced the same way. The @draft suffix only marks the code as a placeholder; whether the record is committed is decided by saveAsDraft alone. A committed record can still come back as pending approval when an approval definition matches it — that is the approval feature, not the import.
The general shape:
{"SalesInvoice": [
  {
    "book": "SalesInvoice$#SINV",
    "valueDate": "01-02-2024",
    "customer": "10011",
    "details": [
      { "item": { "itemCode": "9999", "item": "9999" },
        "quantity": { "quantity": { "primeQty": { "value": 1, "uom": "SRV" } } },
        "price": { "unitPrice": 100 } }
    ]
  }
]}
A sales invoice's lines are its details collection. References — the customer, the item — are written by code. A book or a document term is written as <entity type>$#<code>, as with "book": "SalesInvoice$#SINV": the entity type it belongs to, then its code. The same JSON shape is described field by field in The JSON Shape. The exact structure of each entity is what GetImportSchema returns, and the safest approach is for the client to read an existing record with GetRecord and mirror its shape.
A new record starts from the same blank record a new screen would show, so the user's default-values template fills it first and the imported fields are laid over it — a field the import leaves out keeps the template's value.
Records are persisted through the standard entity gate, so all validations and effects (journal entries, inventory transactions, ...) work exactly as if the record were entered from the screen. If a record fails, the error details are returned to the model so it can correct and retry.
Attachments. An attachment field cannot carry the file itself, so it takes a small object instead: {"uploadId":"<token>"} — exactly the importValue that PrepareAttachmentUpload returned, once the file has been sent to its link — or {"url":"<http or https address>"}, which makes the server download the file itself. Either may add "fileName" to store the file under another name. The url form follows the same rules as in the REST API: no addresses on the server itself or a private network, 50 MB at most by default — see Uploading and Attaching Files. Giving both uploadId and url fails the record; an object with neither — such as the {"id", "fileName", "size"} object GetRecord returns — is ignored and the attachment stays as it is. A plain string, a file path included, is never accepted: it fails the record with an English message explaining the two object forms.
import_PrepareAttachmentUpload — a link to upload a file
The first step of attaching a file to a record. It returns a one-time link the assistant sends the file to, and the value to put in the attachment field afterwards.
| Parameter | Required | Description |
|---|---|---|
fileName | No | The name to store the attachment under, extension included, such as invoice-1001.pdf. When left out, the name the upload carries is used |
The answer carries the uploadUrl, the importValue (already shaped as the object {"uploadId":"<token>"}), the largest file accepted in bytes, and how long the link and the uploaded file stay valid. The assistant then sends the file to the link with an HTTP POST (or PUT), either as the raw request body or as a multipart form file:
curl --data-binary @"invoice-1001.pdf" "<uploadUrl>"
curl -F file=@"invoice-1001.pdf" "<uploadUrl>"
No API key goes with it — the link is its own authorisation. Finally it calls ImportRecord with the attachment field set to the importValue.
- The link takes one file, and expires after 15 minutes if nothing is sent to it.
- Once uploaded, the file stays attachable for 60 minutes, so an import refused by a validation can be corrected and sent again with the same
importValue. - Only the same Nama user who prepared the upload can attach the file.
- The largest file accepted is 50 MB by default; change it with the
ai-upload-max-file-size-mbproperty innama.properties.
import_PrepareAttachmentDownload — a link to download an attachment
The reverse direction: fetch a file already attached to a record so the assistant can save it locally and read it.
| Parameter | Required | Description |
|---|---|---|
entityType | Yes | The entity type of the record |
idOrCode | Yes | The record's business code or id |
fieldId | Yes | The attachment field id as it appears in the import schema. For a field in a detail table, give the full collection.field id |
lineNumber | No | The 1-based line number — required for a field in a detail table |
The record is read through the normal permission checks, so the user must be allowed to see it. A header field is read on its own — a single column — so it costs the same however many lines the record has. A field in a detail table reads the whole record; on a record with many lines, use the by-id tool below instead. The answer carries the file name and size, a one-time downloadUrl, and a ready-made command:
curl -o "<file name>" "<downloadUrl>"The link works once and for 10 minutes; if the download fails, prepare it again.
import_PrepareAttachmentDownloadById — a download link from an attachment id
The same one-time link, prepared from the attachment's own id rather than from a record and a field.
| Parameter | Required | Description |
|---|---|---|
attachmentId | Yes | The id of the {"id", "fileName", "size"} object that GetRecord or FindRecords returned for an attachment field |
It reads nothing but the file, which makes it the cheap way to fetch one line's attachment from a large record: FindRecords lists the lines' attachments, and this tool turns the chosen id into a link — see Moving attachment files. The link is the same as above: it works once, for 10 minutes, with no API key.
It does not check whether the user may see the record the attachment belongs to: any signed-in user who has the id can fetch the file, just as with the attachment links on Nama's own screens. PrepareAttachmentDownload, by contrast, checks access to the record.
A Complete Workflow
The usual pattern an MCP client follows to import data:
- import_ResolveEntityType: "sales invoice" →
SalesInvoice. - import_GetImportSchema: learn the required fields and the invoice-lines structure.
- import_GetEnumValues: the correct constants for enum fields (the discount type, for example).
- import_FindRecords: find the reference codes (customer, item) before using them.
- import_ImportRecord: import as a draft first for review, or save and commit directly.
- import_GetRecord: read the imported record back to verify the result.
Moving attachment files
An MCP tool call carries text only, so the attachment tools never pass a file inside the conversation. They hand the assistant a link instead, and the assistant moves the file over that link with curl. That makes them useful only to assistants that can run commands — Claude Code, or the Code tab of Claude Desktop. A typical exchange, asked to "attach the signed contract to customer CUST001":
- import_PrepareAttachmentUpload with
fileName=contract-cust001.pdf→ anuploadUrlandimportValue={"uploadId":"<token>"}. curl --data-binary @"contract-cust001.pdf" "<uploadUrl>"— run by the assistant on your machine.- import_ImportRecord with
importMode=UpdateOnlyand{"Customer":[{"code":"CUST001","attachment":{"uploadId":"<token>"}}]}. - import_PrepareAttachmentDownload on the same field, if you want to check what was stored.
Fetching an attachment from a detail line of a large record — say one line's file on a document with thousands of lines — goes the other way round, so the whole record is never read:
- import_FindRecords with
fields=<collection>.<field>andcriteria=code,Equal,<code>,AND;→ one{"id", "fileName", "size"}per line. - import_PrepareAttachmentDownloadById with the
idof the line you want → a one-timedownloadUrl. curl -o "<file name>" "<downloadUrl>".
The links point at two endpoints that live in the services web app next to the MCP endpoint:
http[s]://<server-ip-or-domain>/basic-services/ai-upload
http[s]://<server-ip-or-domain>/basic-services/ai-download
The second is the same endpoint that serves the single-use links of rendered reports. Both links are absolute, built from the address the MCP client used to reach the server; the X-Forwarded-Proto and X-Forwarded-Host headers are honoured. When that address is not the one the assistant's machine can reach — behind a reverse proxy, typically — set ai-file-download-base-url in nama.properties to the server's public address, and every link is built on it instead.
Release 20261007 or later
The attachment tools, and attachment values in ImportRecord, exist only on servers from release 20261007 onwards.
Messages you may see
When the server refuses a connection it answers every request with HTTP 401 and a text that starts with MCP authentication failed:. Clients usually show it as a failed connection; the text is in the connection's details or log. These messages exist in English only, so they read the same on an Arabic installation.
| Message | Why | What to do |
|---|---|---|
| MCP authentication failed: Missing API key | The request carried no X-API-Key header (or apiKey / clientId parameter) and no bearer token. | Add the X-API-Key header to the client's configuration, spelled exactly. |
| MCP authentication failed: Invalid API key | The key matches no committed API Credentials record — mistyped, from another server, or the record was deleted. | Copy the API Key (Client Secret) again from the record on this server (tick View API Key and save). |
| MCP authentication failed: Invalid API secret | X-API-Key carried the record's Client Id (Can Be Ignored), and X-API-Secret was missing or wrong. | Send the API Key (Client Secret) in X-API-Key and drop X-API-Secret. |
| MCP authentication failed: Your API key expired on {0} | The record's Valid to date has passed. | Extend Valid to on the record, or issue a new one. |
| MCP authentication failed: Your API key can be used only after {0} | The record's Valid from date is still in the future. | Wait, or bring Valid from forward. |
| MCP authentication failed: The provided API key is prevented from login | Prevent Login is ticked on the record. | Untick it if the connection should work. |
| MCP authentication failed: MCP subscription expired on {0} | The MCP subscription in the server's licence ended on that date (written yyyy-MM-dd). Everything else may be fine — the same key worked the day before. | Renew the MCP subscription with Nama; the key does not need to change. |
An HTTP 404 at /basic-services/mcp is a different matter: the AI module is not installed on that server, so there is no MCP server to answer.